Round-the-clock cloud & database monitoring
24/7 monitoring.
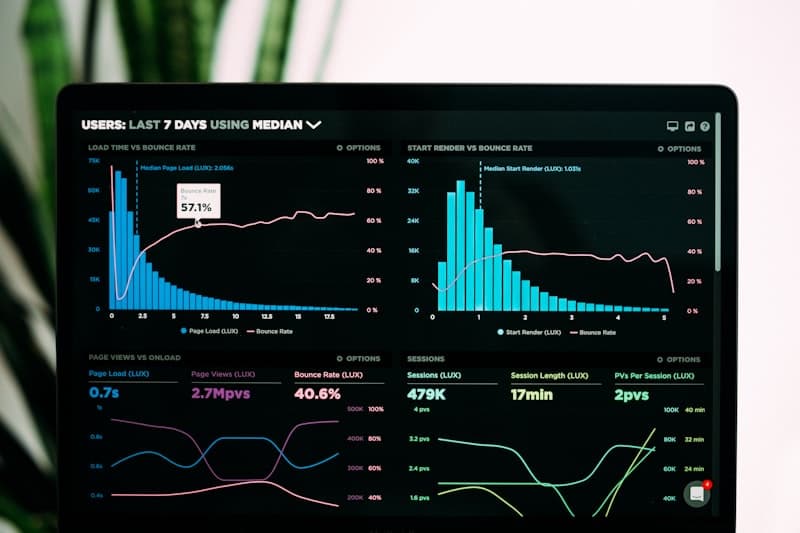
Never miss a critical issue with our 24/7 monitoring services. We provide real-time alerting, performance tracking, and proactive incident response for your cloud infrastructure and databases.
- Real-Time Infrastructure Monitoring
- Database Performance Monitoring
- Custom Alert Rules & Escalation
- Log Aggregation & Analysis
- Uptime & SLA Monitoring
- Performance Dashboards & Reporting
- Incident Response & Root Cause Analysis
- Capacity Planning & Forecasting
Technologies we use
The tools we trust.
09 technologies
 Prometheus
 Grafana
 Datadog
 New Relic
 Nagios
 Zabbix
- AWS CloudWatch
 Elasticsearch
 Wazuh
FAQ
Questions, answered.
We monitor server health, CPU/memory/disk usage, network traffic, application performance, database queries, API response times, error rates, and uptime. We also track business-critical metrics customized to your application.
We use industry-standard tools including Prometheus, Grafana, Datadog, New Relic, Nagios, Zabbix, and AWS CloudWatch. We select the best combination based on your infrastructure and create custom dashboards for real-time visibility.
Our response times depend on severity — critical incidents (P1) are acknowledged within 5 minutes and resolved within 1 hour. We provide automated alerting, escalation procedures, and post-incident root cause analysis for every significant event.
Yes, we support hybrid monitoring setups covering cloud resources, on-premise servers, containers, databases, and applications. We create unified dashboards that give you a single view across your entire infrastructure.
Absolutely. We provide weekly and monthly reports covering uptime statistics, performance trends, incident summaries, capacity forecasts, and optimization recommendations. All reports are accessible through real-time dashboards as well.
Start something
Let's buildwhat’s next.
Leave your email and our team will get back to you within one business day.
Or write to sales@sparkcurv.com